We spoke with students and university staff, then built a RAG assistant to help applicants find clear information. I led development and built a 125-question evaluation set. Python, FastAPI, ChromaDB and Angular.
Starting with the people using it
Students wanted quick, clear answers about admissions. Our surveys and interviews with administrative staff helped us understand where information was hard to find. We then tested a prototype with people who would use it.
How it works
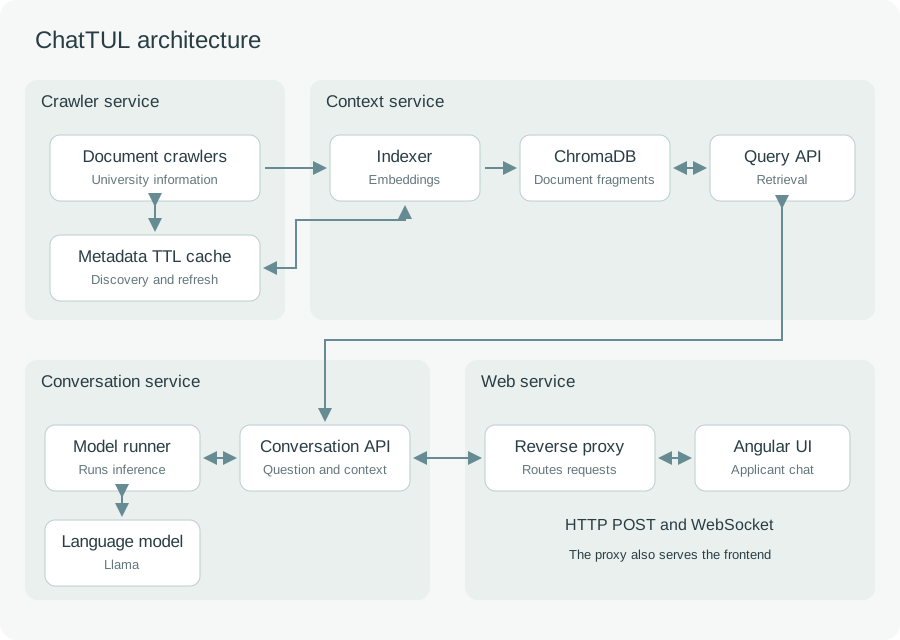
A crawler collects university information. SentenceTransformers embeddings and ChromaDB retrieve relevant passages, which the language model uses to answer through FastAPI services and an Angular interface. We initially used Llama 3.1 8B, quantized to 6 bits, and also tested a 70B model.
Testing the answers
The presentation reported 86.5% faithfulness, 83.3% context recall and 75.6% context precision. These measure different parts of retrieval and answer quality. Questions outside the admissions domain, repeatable answers and limited computing resources remained important challenges.
Keeping each part understandable
We separated document collection from retrieval and conversation. The crawler discovered and refreshed university pages. The context service indexed their content and exposed a query API backed by ChromaDB. The conversation service combined the question and retrieved context, then passed them to the model runner. The web service connected this to the Angular frontend through a reverse proxy.
What the evaluations tell us
The final presentation reported these RAGAS values on 30 samples drawn from a 100-question set, using a 70B model. I later described a 125-question evaluation set in my CV. These are different evaluation snapshots, so I would not treat the slides as evidence that every one of the 125 questions was scored in that run.